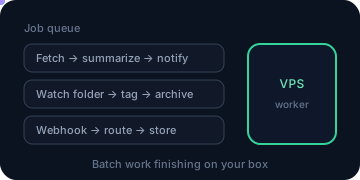
Separate orchestration, UI, model, and accelerator
| Layer | Examples | Budget note |
|---|---|---|
| Orchestration | n8n / schedulers | CPU/RAM for workers—not VRAM |
| Application UI | WP, dashboards, agents UI | Auth/TLS exposure risk |
| Model runtime | Weights + KV cache | Disk ≠ resident RAM |
| Accelerator | None / external API / other-cloud GPU | ScalaHosting captures showed no Cloud GPU SKU |
Why Managed Cloud is usually the wrong AI appliance
Research captures did not surface a ScalaHosting Cloud GPU product. Managed free support excludes most additional server software installs except narrow, case-by-case approvals. SPanel and WordPress packaging optimize sites, mail, and databases—not model VRAM. Marketing that mentions “AI” inside SShield is a security product claim, not a local inference appliance.
If you need serious local LLMs or CUDA workflows, start with a GPU-capable cluster such as Vultr AI apps or keep inference on an external API while ScalaHosting (or another host) runs only orchestration.
Light Unmanaged CPU experiment
Prerequisites: an accepted Unmanaged host, measured free RAM/disk, and an independent export destination. Editorial hypotheses only—never “Build #1 runs every 7B model”:
- Consider ≥4 GB RAM for one tiny quantized model and one short request if OS + runtime still fit.
- Consider 8 GB for a modest experiment if measured weights + KV + OS fit.
- Stop on swap thrash, OOM, or disk pressure; exit to a smaller model, lower context, external API, or a GPU host—not endless resize on ScalaHosting alone.
# Example discovery only — pin images/tags from current upstream docs at your draft time.
free -h
df -h
# Prefer loopback binds for any local model API; do not publish unauthenticated inference ports.
No tokens/sec claims. Record tag, download size, RAM before/after, and the stop reason privately.
Connect automation without publishing the model
Prefer managed n8n packaging with hosted models when local weights are unnecessary. On a DIY host, keep model endpoints on a private Compose network or loopback; never open them “temporarily” to the internet. Hosted model APIs are not “local” merely because your VPS is yours—track credentials, egress, and provider data terms separately.
Fit / no-fit and next decision
Fit: deliberate tiny Unmanaged CPU experiment with export discipline.
No-fit: production multi-model, GPU needs, expecting managed Ollama installs, or shopping by tokens/s marketing.
Next: n8n operations, local AI hub, Vultr AI, review.